

By Markus Schwarzer, CEO of Cyanite
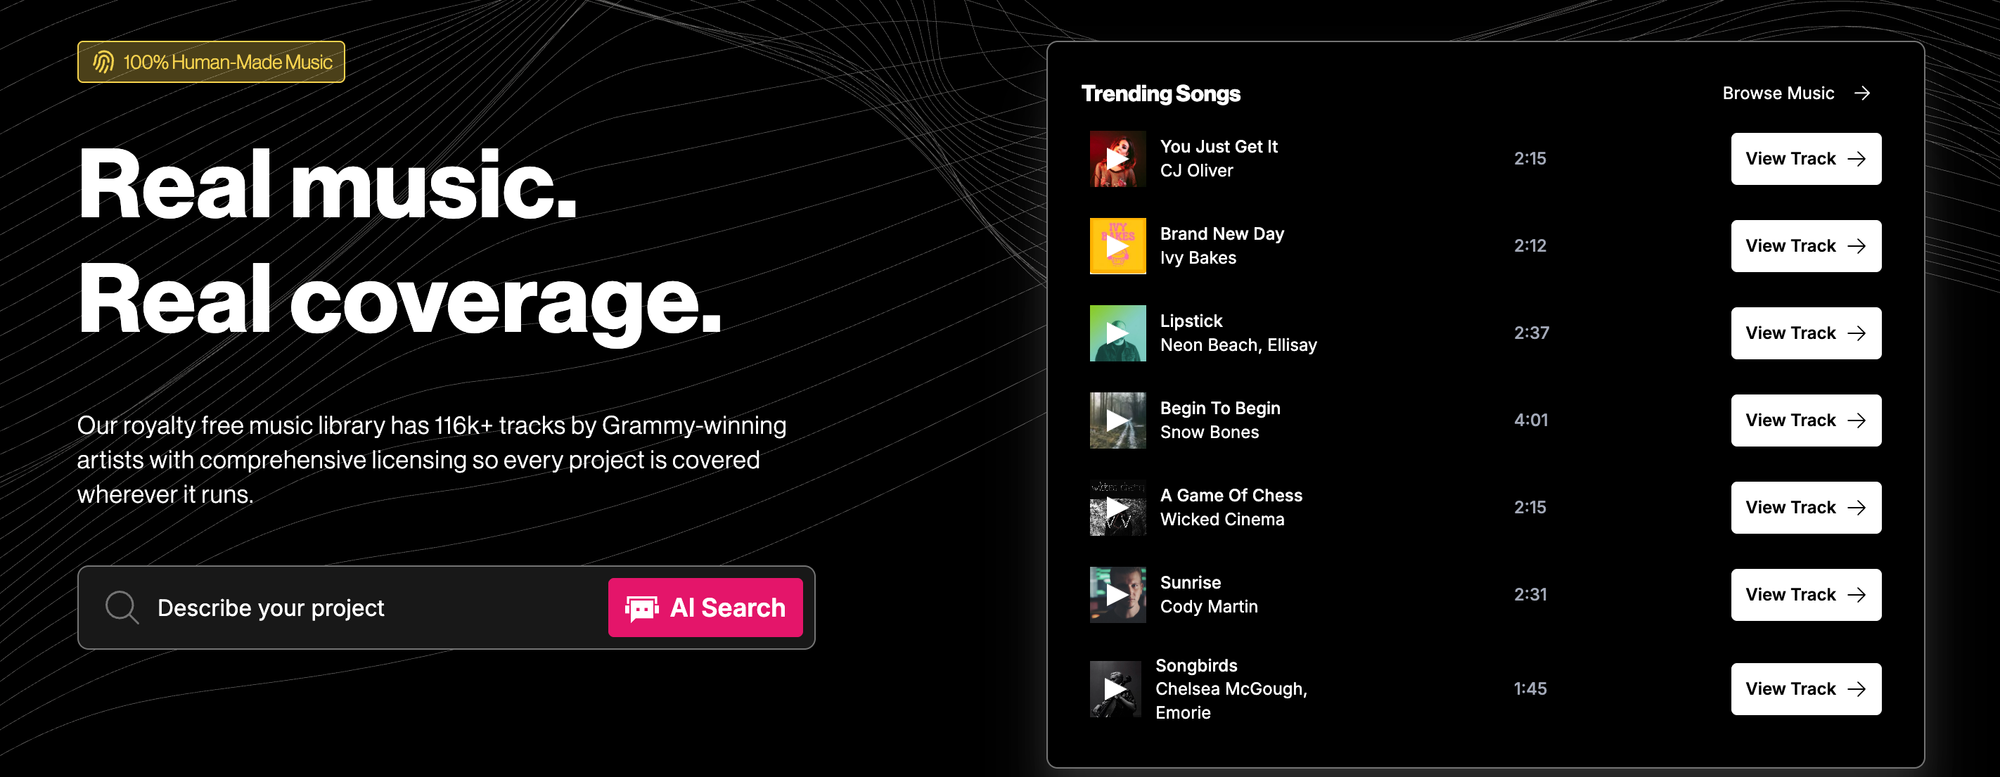
I was browsing the Epidemic Sound website when I noticed they had added conversational search. It was so good that, for a brief moment, I was convinced they’d found a much better solution than ours. We might as well close shop, I thought.
Then I looked into what was powering it and realized, oh… that’s us.
It wasn’t a different technology. It was Cyanite’s music understanding and search working underneath an LLM. We’d spent the past months improving our tagging models, while, at the same time, the Epidemic Sound team had been building the conversational search experience their users needed on top of them. They took the foundation we provided and extended it into a product that fit their audience.
That moment made me realize where this is all heading. As we move into the agentic era, people will build entirely new ways to work with their catalogs. But none of those workflows function unless machines can understand the music and find it.
Get that layer right, and the rest becomes much easier to build. I'll prove it to you.
What has actually changed
Across the music industry, I keep hearing the same frustration: people spend a huge part of their day on repetitive work that feels impossible to delegate because the workflow isn’t written down anywhere. The workflow is based on years of experience that lives almost entirely in one person’s head. I’ve heard them say they’d have to clone themselves to get the work done faster.
For a long time, software could only automate workflows that were explicitly defined. The moment a process depended on someone’s accumulated experience, it became much harder to delegate. Language models changed that. Give one enough context, and it can already mimic 80–90% of a text-based workflow. It won’t get every decision right, but it doesn’t have to. If it can handle the repetitive work, that’s already enough to save hours.
I have a friend who works in creative sync at a music publisher. Every new track that comes in ends up in one of about 30 folders she created over the years, depending on whether it fits luxury brands, automotive campaigns, FMCG, uplifting music, or whatever else makes sense to her. It’s her own taxonomy. It makes perfect sense to her because she built it, but nobody else really understands it.
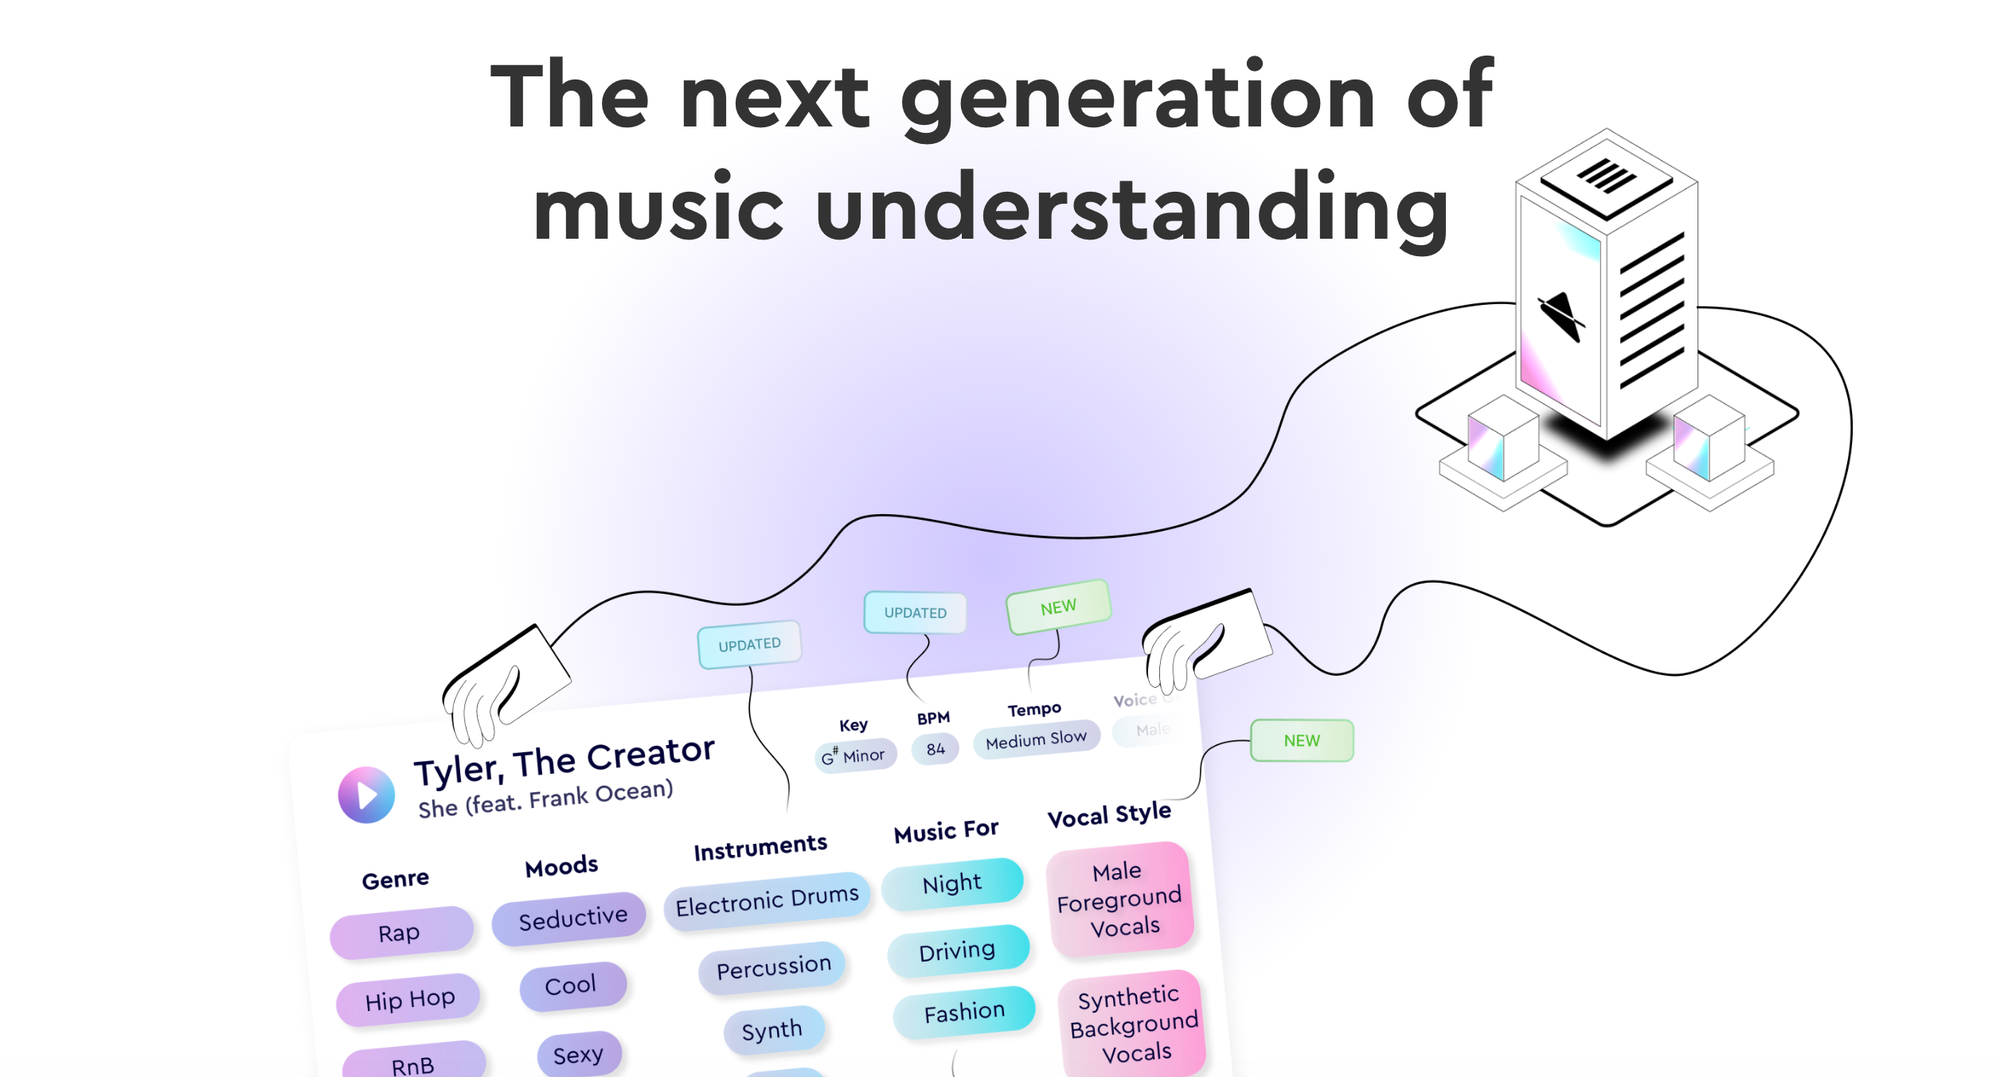
At first glance, this looks like exactly the kind of workflow an LLM should be able to take over. The problem is… LLMs today can’t adequately understand music. They need structured music metadata describing sound and lyrics to recognize the patterns behind her decisions. Give it enough data from tracks already sitting in those folders and it will be able suggest where any new song belongs before she ever listens to it.
That’s the clone she’d always wished she had. But that only works because the LLM isn’t making sense of the music on its own. It’s reasoning from structured descriptions of the music and the patterns they reveal.
Why structured music understanding matters
Language models work from the information they’re given. The more relevant that information is, the better the result. The same applies to music. Before AI can become useful, a recording has to be translated into information a machine can reason with, information that reflects how the catalogue is actually used, not just what the track sounds like.
Think back to my friend in creative sync. Her folders aren’t simply collections of songs with similar characteristics. They’re the result of years of placing music for real clients. Every track she files away adds another example of what belongs together in her world. An AI might know that a track is energetic, guitar-driven, and around 120 BPM, but that alone doesn’t explain why she’d choose it over another. Give it the structured data for the tracks already sitting in her folders, though, and it begins to see the same patterns she does, learning how those characteristics relate to the way her catalogue is actually used.
That was exactly what I saw on Epidemic Sound’s website. The AI wasn’t replacing the music understanding underneath. It was using that understanding together with retrieval to make the catalog searchable through conversation.
That is why structured music understanding matters more, not less, as AI enters more workflows. It turns every file into a consistent description, giving every agent and workflow the same starting point. So, search, recommendations, and automation all build on that same foundation.
A conversational search system can interpret a request in natural language and connect it to the right tracks. A publisher can sort new uploads into an existing taxonomy. A creative team can search for music that fits a specific brief. Different teams ask different questions, but they’re all drawing from the same catalog, and you pay the cost of understanding the music once so every future music AI workflow can query the same structured representation.
What this looks like in practice
What I saw at Epidemic Sound isn’t an isolated example. The LLM handled the text understanding while Cyanite dealt with structured music understanding behind the scenes to find, compare, and refine the right tracks.
Soundstripe has taken a similar approach. Users can search in natural language then refine their request through conversation. The language model manages that back-and-forth, asking follow-up questions, interpreting intent, and adjusting the search as the conversation evolves, while Cyanite provides the music understanding that keeps the search grounded in the catalog.
BeatStars applies the same idea in a completely different workflow. Every month, hundreds of thousands of new tracks are uploaded to its marketplace. Structured audio metadata gives every new upload a consistent description, making that catalog immediately usable for search, recommendations, and future AI applications.
These companies are solving different problems, but they have all arrived at the same conclusion. AI makes the interaction more natural. A consistent understanding of the catalog makes those interactions useful.
Looking ahead
The agentic era will bring new ways of working with music. Some will change how people search and discover music. Others will automate work that still happens manually today.
Every one of those workflows depends on a machine being able to work with the music in the catalog. The better that foundational layer, the more useful AI becomes, regardless of how the interface evolves.
That’s why AI needs both structured music understanding and retrieval. Together, they give AI a reliable way to understand, search, and reason over music, so teams can build the workflows that make sense for their business.
If you’re building for the next generation of music workflows, start with structured music understanding — the foundation they’ll all depend on.
Markus Schwarzer is the CEO of Cyanite. Cyanite gives music companies — and the AI agents now built on top of them — a deep, structured understanding of music: powering search, recommendation, and metadata at scale.